Red Canary trades S3 and Postgres for ScyllaDB to handle endpoint telemetry at scale
The security vendor's Linux EDR team replaced cloud storage and a relational database with a write-optimized NoSQL system to cut costs and latency when processing hundreds of thousands of small data payloads from endpoints.
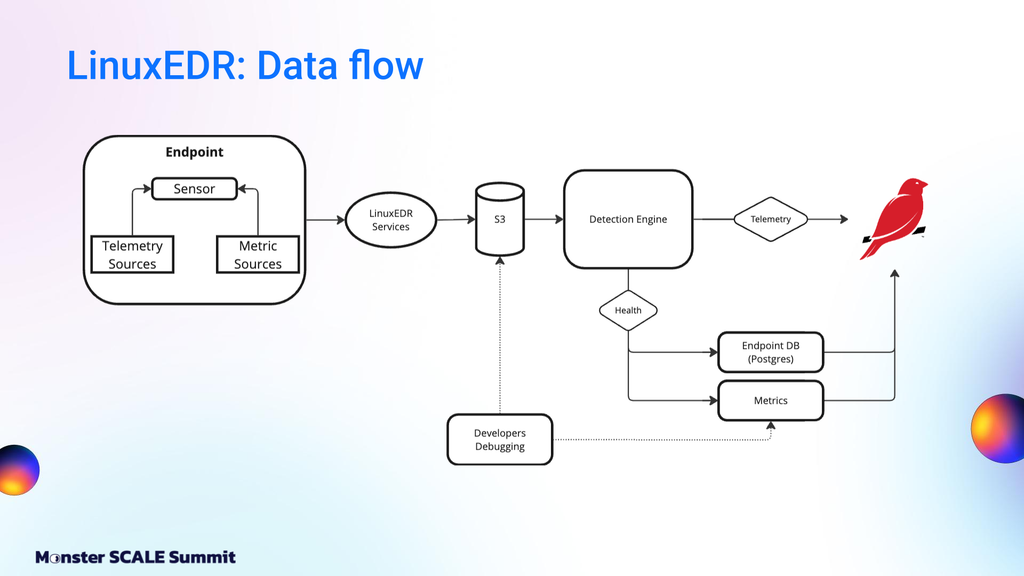
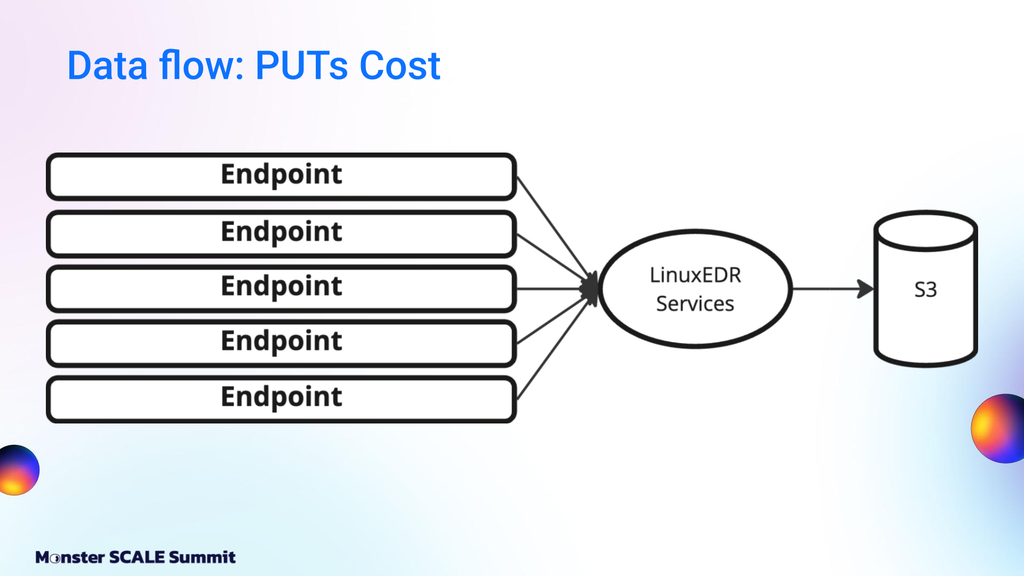
Managing vast quantities of diminutive data payloads presents a significant operational challenge at Red Canary. The company's Linux Endpoint Detection and Response (EDR) sensors operate across hundreds of thousands of endpoints—virtual machines, laptops, and EC2 instances—continuously producing small telemetry records that document file modifications, process activity, and network traffic, alongside periodic health status reports. Transmitting each individual payload to Amazon S3, where AWS charges for every PUT operation, proved prohibitively expensive as the deployment expanded.
Consolidating smaller payloads into larger files before S3 upload reduced expenses, yet introduced fresh complications: rigid file-size constraints, postponed data visibility, and difficulty isolating particular endpoint records for troubleshooting. The LinuxEDR team ultimately discovered an unconventional remedy: deploying ScyllaDB, a write-optimized database, to retain large volumes of small data. This shift decreased both latency and operational costs.
Andres Medina, staff software engineer on the LinuxEDR team, presented the team's progression from S3 and Postgres through a Firehose buffer layer to ScyllaDB at the Monster Scale Summit, detailing the technical lessons acquired throughout the migration.
Addressing health check data flow challenges
Medina's group selected health check data as the initial focus for pipeline improvements. This component represented a lower-risk testing ground compared to actual telemetry information.
Problem 1: cost
The expense issue demanded immediate attention. "S3 charges a flat fee per S3 PUT, which occurs for every payload upload," Medina explained. "So if we have hundreds of thousands of endpoints, we're being charged for hundreds of thousands of S3 PUTs."
The team attempted a temporary solution by introducing a buffering layer. AWS Firehose and Kinesis aggregated small data streams into larger files, writing to S3 only after reaching a specified size threshold. While this reduced costs, it created additional problems:
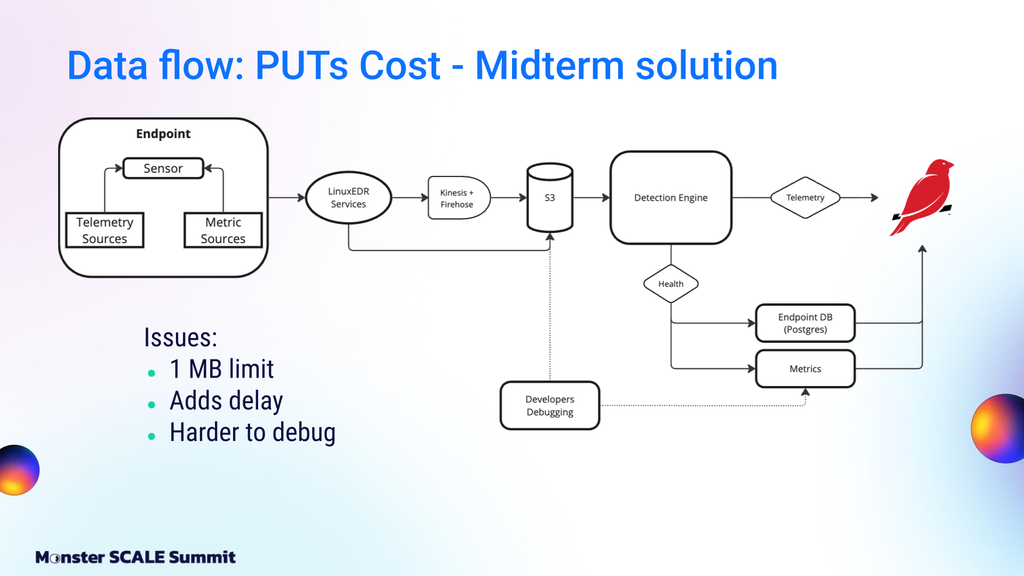
- Firehose and Kinesis enforce a strict one-megabyte-per-shard limit, preventing larger files from fitting within constraints.
- Data visibility suffered delays; previously health information transferred to S3 immediately, but now required waiting for the threshold to be reached.
- Locating individual endpoints became problematic when numerous endpoint identifiers were combined in large files, complicating troubleshooting across customer fleets.
Problem 2: database scalability
Postgres, which stored endpoint metadata, could not handle the scale demands. "Sometimes a large customer might restart a chunk of their fleet," Medina noted. "That means that many endpoints will try to check in at very similar times, causing a spike of writes in the database." Request throttling became necessary to prevent sudden write bursts from destabilizing the system. Rather than pursuing incremental database tuning, the team sought a more durable solution.
Pursuing a sustainable architecture
The team established requirements for their new approach:
- Capacity to maintain their substantial and expanding throughput
- Faster data visibility within their portal interface
- Reduced operational overhead
ScyllaDB Cloud emerged as the selection, specifically using the Bring Your Own Account (BYOA) deployment model. Medina stated, "We installed it in our own AWS account, in a separate account from our remaining data to reduce any risk there. That way, ScyllaDB can still manage that cluster without having access to our data." The migration proceeded in two stages: first replacing Postgres, then replacing S3.
Replacing Postgres
Transitioning away from Postgres proved more straightforward than the subsequent S3 replacement. Each sensor event generates a single row, and the web portal consistently queries data in time-series fashion—retrieving active endpoints for a customer across specified periods. Nevertheless, the fundamental differences between Postgres and ScyllaDB required the team to address tombstones and uneven data distribution.
In ScyllaDB, deleted data leaves behind a timestamped marker termed a tombstone, preventing data resurrection if a node fails to receive a deletion message and later restores outdated information during cluster repair operations. For Red Canary's ephemeral endpoints—which remain active only briefly—tombstones created substantial problems. Medina explained: "Some clusters might scale up for an hour and then scale back down, which means an endpoint is alive for a very small amount of time. That meant some customers had partitions that were mostly just tombstones. When you query it, ScyllaDB has to iterate through all these tombstones, making our latency worse than it should be."
The resolution was straightforward: since the team retained no deletion requirements, tombstones were unnecessary. They removed tombstones from query operations by implementing a brief table TTL and accelerating tombstone garbage collection. Query performance improved accordingly.
A second challenge emerged from wildly inconsistent data volumes across customers. Some maintained dozens of endpoints while others operated hundreds of thousands. To prevent hot partitions in ScyllaDB, Medina's team implemented a bucketing approach, dividing each customer's data into numbered "buckets" distributed across shards. When retrieving customer data, the system determines bucket count and queries all buckets simultaneously for improved response times.
Replacing S3
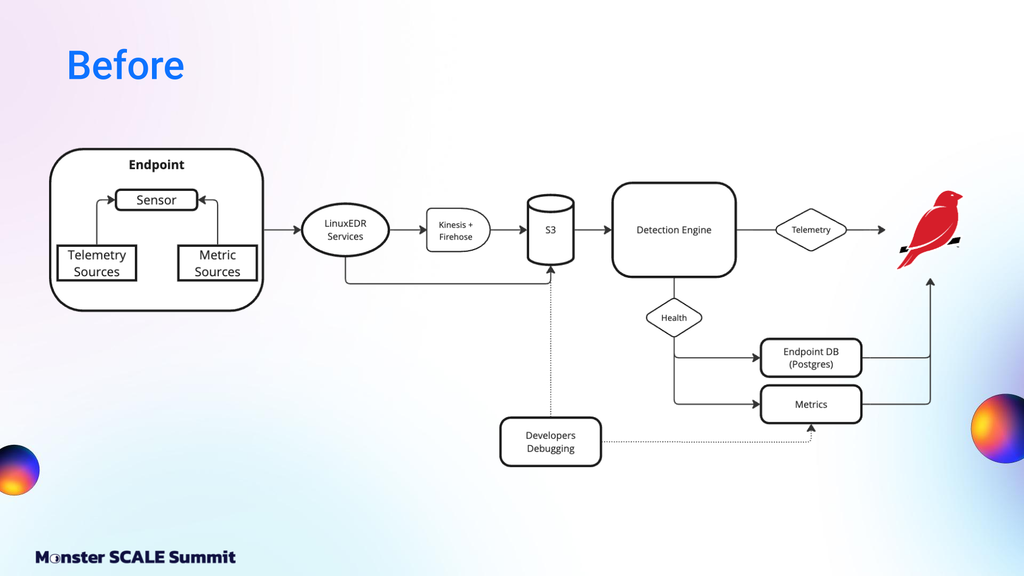
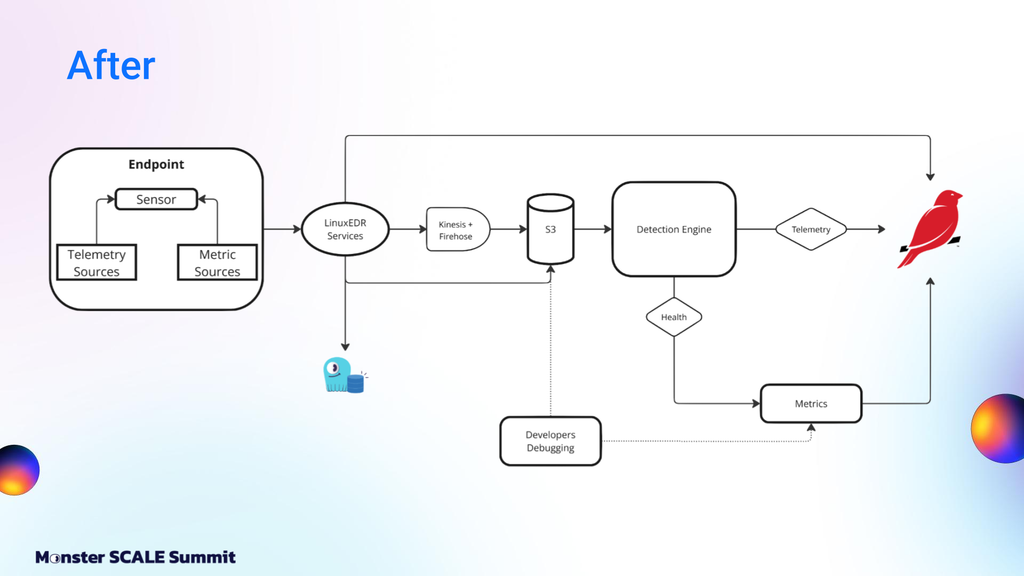
Substituting S3 with ScyllaDB represented a more unconventional undertaking, involving higher throughput and less predictable access patterns. Medina noted, "It's not a service trying to query in one way. Instead, it's developers debugging." One predictable pattern existed: developers typically debug individual sensors in isolation. Consequently, "sensor ID" became the partition key for queries. This choice served a strategic purpose: "One of our biggest reasons for wanting to do this was to see if ScyllaDB could also be used for our detection data in the future." Health data, with comparable throughput and lower operational criticality, offered a controlled environment for testing broader ScyllaDB adoption.
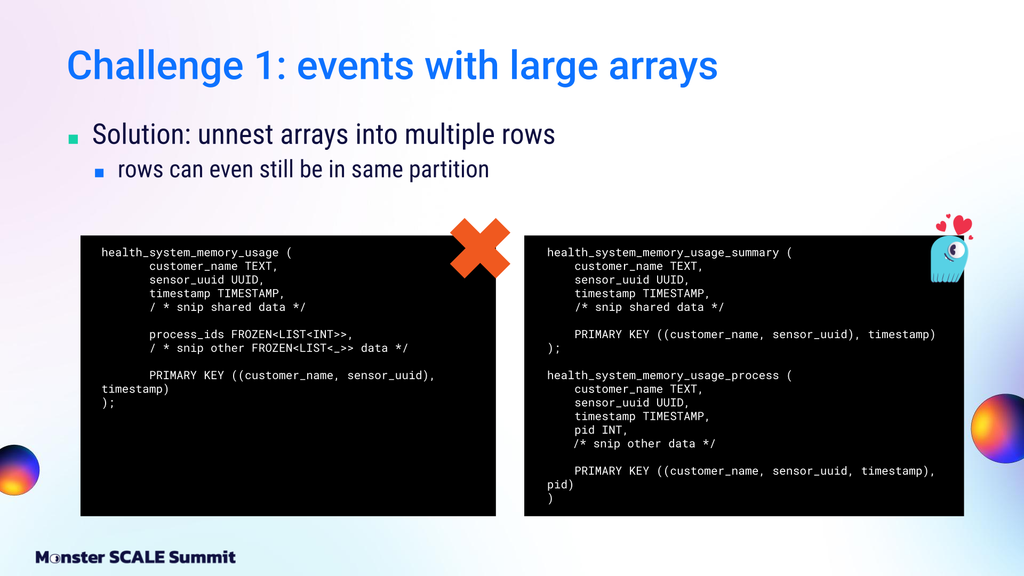
Events contained extensive arrays tracking memory consumption across processes at each endpoint. With thousands of simultaneous processes on some endpoints, rows became unwieldy. The solution involved unnesting arrays and storing process-level memory data in a separate table while maintaining partition co-location for straightforward querying. Medina added, "We can still put every row in the same partition so that our querying is still easy enough, as long as the partition doesn't get too big (too many rows)."
Batching presented the next challenge. The team preferred batching writes rather than executing individual health event insertions, minimizing network round trips. Batching efficiency improves when all statements belong to identical partitions. Ideally, statements would be partitioned upon receipt, but the ScyllaDB Rust driver lacked this capability.
Wrangling the Rust driver
The Rust driver did not expose prepared statements with pre-serialized values (bound statements). Obtaining a partition for a statement required serializing values once to compute the hashed token, then serializing again for execution. Maintaining unserialized values alongside statements created Rust type system complications—collections require uniform types, but different statements carry different value types. Once serialized, values become byte streams compatible with unified collections.
Medina described his solution: "To get around this, I forked the Rust driver to add the idea of a bound statement and then a bound batch, which is just a collection of statements. With this now in place, we can ask the bound statement what its token is without having to reserialize it, and then execute it again without reserializing it. A second benefit is that we can separate CPU work from I/O work. In Rust, you mostly use Tokio for I/O operations, and doing CPU work there can block the runtime and reduce efficiency. So now we can do all of the CPU work in a CPU-bound worker using Rayon, and then we send it back to Tokio when we're done. Then in Tokio, you can just do the I/O for the batch execution."
When we made this change, our average time to process a file dropped from about 150 milliseconds to 50 milliseconds — a drop of about 60%.
Andres Medina
Medina added, "Of course, this is for our use case, so your mileage may vary."
Measuring the results
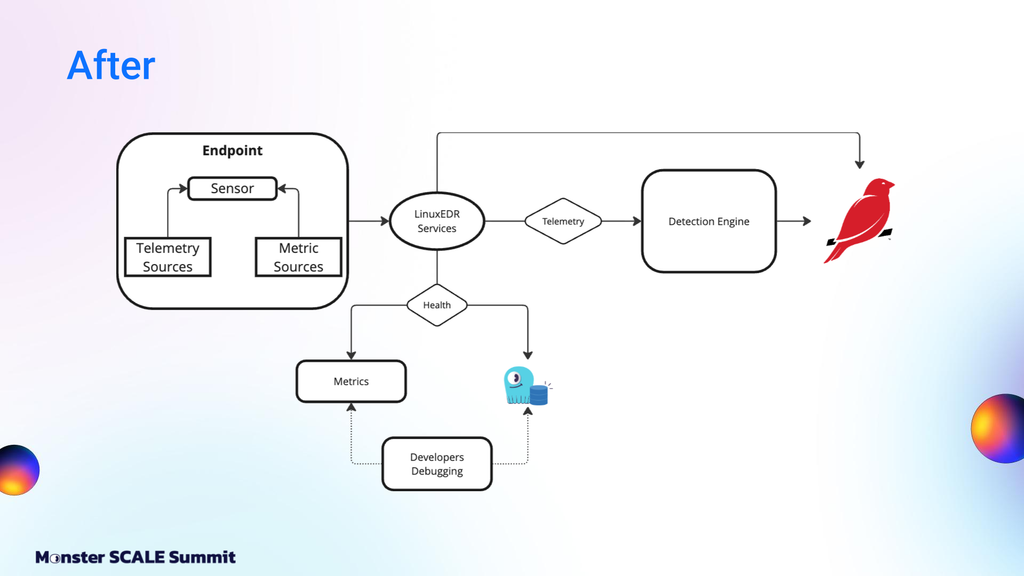
The LinuxEDR services now manage health data independently, no longer routing it to the engine. ScyllaDB houses all check-ins and health metrics, with a separate metrics database remaining for now but potentially subject to replacement. The portal queries services for active endpoint lists, and developers can directly query ScyllaDB for debugging purposes.
The team achieved substantial per-endpoint cost reductions. Batching elevated I/O throughput, delivering approximately 20X fewer writes relative to inserted rows (670K rows per second but only 36K writes per second through batching). Portal endpoint retrieval now completes in seconds rather than minutes for their largest customers. Medina observed, "Each query to ScyllaDB is in the double-digit millisecond range."
Looking ahead
"Since the transition has gone fairly smoothly, we're now exploring using it for data that is more critical. One of my team's main goals is to store our detection data in ScyllaDB to avoid sending data that doesn't need to go to the engine. Also, we're looking at ways to use it outside my team to replace some uses of OpenSearch, which has been giving us issues with cost, performance, and sometimes paging…no one likes being paged. Ideally, I would also like to merge the fork at some point so I don't need to rebase the driver on every new release," Medina said.