Hugging Face routes AI inference through OpenRouter in partnership deal
The two companies have partnered to improve model inference reliability for developers, with OpenRouter now handling request routing across multiple providers for Hugging Face's platform.
Hugging Face and OpenRouter announced a strategic partnership on Monday aimed at delivering faster and more dependable AI model inference to the developer community.
Under the arrangement, OpenRouter will manage the routing of language-model requests across third-party providers, selecting among them based on pricing, performance and reliability metrics. This represents a shift from Hugging Face's previous approach, which relied on its own routing system launched in January 2025 as part of the Inference Providers service. That initial system connected developers with four providers—Fal, Replicate, SambaNova and Together AI—but lacked failover capability; if a provider experienced issues, the request would fail entirely.
The new setup enables automatic rerouting to alternative providers when problems occur, substantially reducing failed requests for developers. Hugging Face co-founder and CEO Clément Delangue framed the collaboration as evidence that AI companies can work together to make open-weight models more accessible, with each organization concentrating on its core competencies.
Too many people treat AI as a zero-sum race. Open-source is winning by doing the opposite: collaboration over competition!
Clément Delangue, Hugging Face co-founder and CEO
Delangue added, "Hugging Face for storage and collaboration. OpenRouter for inference."
Stripe, Nvidia and the bigger picture
The partnership announcement arrives shortly after Stripe finalized its acquisition of OpenRouter, a transaction initially disclosed in August with a reported valuation exceeding $7 billion. Meanwhile, Hugging Face itself is undergoing acquisition by Nvidia, the AI chip manufacturer, in a deal valued at nearly $13 billion. Nvidia has recently faced scrutiny following the resignation of former CEO Jensen Huang, who stepped down last week amid controversy.
The OpenRouter integration went live immediately, initially encompassing 160 models from 38 AI research organizations. For Hugging Face, this arrangement eliminates the need to maintain its own routing infrastructure while providing developers with more stable access to these models.
Practically speaking, developers can continue interacting with AI models directly on Hugging Face's model pages. New interface capabilities enable them to evaluate providers by cost, latency and availability, and review performance data to inform their selection. The connection also operates bidirectionally: OpenRouter users can now transmit records of their model requests to Hugging Face Storage Buckets for analysis, dataset construction and model preparation.
From OpenRouter's perspective, the integration provides direct access to Hugging Face's substantial developer base, potentially channeling additional inference volume—and corresponding revenue—to its parent company Stripe.
Hugging Face intends to permit developers to link their OpenRouter accounts directly to its platform and broaden the integration to encompass additional AI tasks, though no timeline has been specified for these expansions.
In announcing the partnership, OpenRouter's director of product marketing Sasha Blumenfeld characterized it as an extension of the company's founding objective.
We built OpenRouter so developers can reach many models and providers through one API, use the best model for each task, and count on it to respond.
Sasha Blumenfeld, OpenRouter director of product marketing
Blumenfeld continued, "Starting today, that extends to everyone building on Hugging Face."
How OpenRouter chooses providers
The integration builds on a routing system overhaul OpenRouter unveiled in October, which transformed how its infrastructure determines where to direct inference requests. Rather than relying primarily on advertised pricing, the system now continuously evaluates actual provider performance, considering response latency, costs and uptime before routing each request. Should a provider become saturated or unresponsive, OpenRouter automatically redirects traffic and retries failed requests with alternative providers.
OpenRouter reported that these changes produced a 46% reduction in capacity-related errors, shortened initial token generation latency by 16.9%, and boosted token generation speed by 16.3% in testing. The tradeoff came in the form of a 6% increase in average cost per request, though these metrics specifically reflect the October routing overhaul.
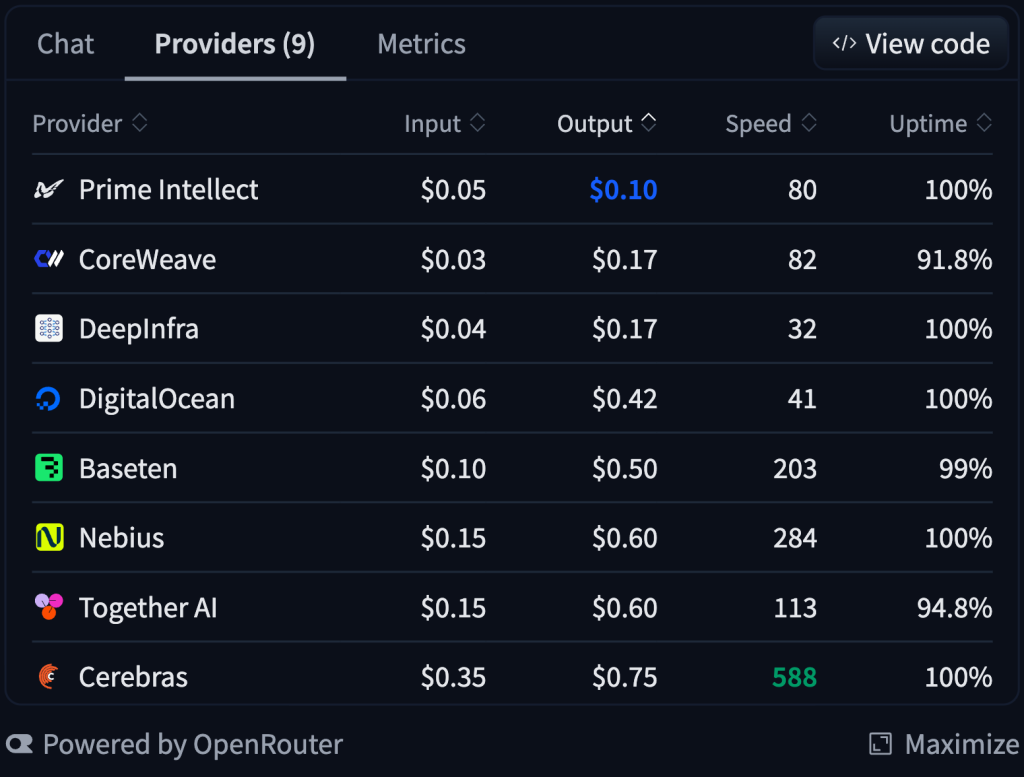
Developers using Hugging Face today can opt to prioritize lower costs, faster responses, or allow OpenRouter to make the determination. The interface displays available providers for each model alongside their respective costs, speeds and recent availability, enabling developers to compare before submitting a request.
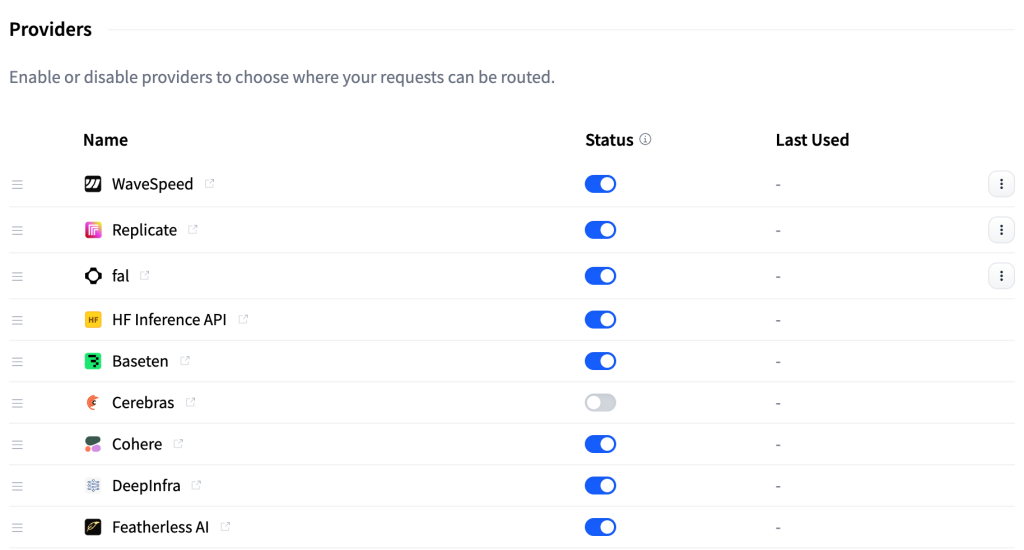
Developers retain the ability to exclude specific providers through account settings, preventing requests from reaching those companies. Teams can implement identical restrictions across all requests charged to their organization.
A significant limitation exists: developers can no longer supply their own third-party provider API keys for language-model requests through Hugging Face. Such requests must now be billed through Hugging Face itself, though developers can still select particular providers. Hugging Face commits to passing through the underlying providers' prices without adding its own margin.
The integration currently covers language models exclusively. Image, video and audio generation continue operating on Hugging Face's existing infrastructure.
The rise of open-weights
This partnership occurs against the backdrop of rapidly expanding adoption of open-weight models as economical alternatives to offerings from the largest frontier AI labs. In September, reporting indicated that open-weight models represented 60% of OpenRouter's US token consumption in August, with models developed in China driving the majority of that usage.
That same month, another significant milestone occurred: open-weight models processed a plurality of tokens on Vercel's AI Gateway for the first time, capturing 56% in August compared to just 7% in December 2025. Nevertheless, they accounted for only 14% of estimated expenditure, while Anthropic alone represented 64%.
The trajectory has persisted. According to OpenRouter's October analysis, open-weight models comprised 71.7% of tokens processed by its 50 most-used models at the end of September, up from 26.8% one year prior. Weekly token consumption for open-weight models expanded more than sixtyfold during that interval.
Vercel's October AI Gateway report reflected comparable trends, with open-weight models accounting for 71.5% of tokens in September. Their share of estimated spending also increased to 23%, though proprietary models continued capturing the majority of spending flowing through the platform.
In its Monday announcement of the OpenRouter partnership, Hugging Face contended that developers frequently do not require the most sophisticated AI models, particularly when less expensive alternatives adequately serve their requirements. The company noted that open-weight models cost approximately four times less on average than proprietary counterparts.
The best open-weight models still trail the best proprietary ones on the hardest benchmarks. For a lot of workloads, that trade-off is worth it.
Hugging Face
The expanding demand for open-weight models presents a commercial opportunity for both Hugging Face and OpenRouter to capture additional market share, enabling developers to select among competing providers based on cost and performance characteristics.