Marketing sites are now products: securing them against AI agents
As AI agents increasingly interact with marketing websites—building pages, scraping content, analyzing visitor data, and optimizing performance—companies must treat these sites as products with security requirements that match their expanded role.
Marketing websites once welcomed two categories of visitors: humans and search engine crawlers. Today's landscape is far more complex. One agent constructs a page, another extracts its content, a third distills it for prospective buyers, and a fourth refines it based on traffic patterns from the previous day. Some of these agents operate under your control; many do not.
This shift transforms a marketing site from a static asset into a functioning product with agent users. Products require product-level security. Marketing sites typically operate as public resources without authentication barriers, making them vulnerable to adversaries targeting three distinct integrity dimensions: what the site communicates, how that communication reaches browsers, and what data it collects about visitors.
Five agent roles, three integrity concerns
Five categories of agents interact with marketing sites in distinct ways:
- Agents that construct pages and site infrastructure
- Agents that read or extract site content
- Agents that examine visitor behavior data
- Agents that refine site performance based on that data
- Adversarial agents designed to compromise the site
Each touches at least one of three protection priorities:
- Content—the text, links, and messaging the site displays
- Delivery—the mechanisms through which content reaches users, including DNS, redirects, third-party code, hosting infrastructure, and publishing workflows
- Signal—visitor behavior data and the decisions derived from it
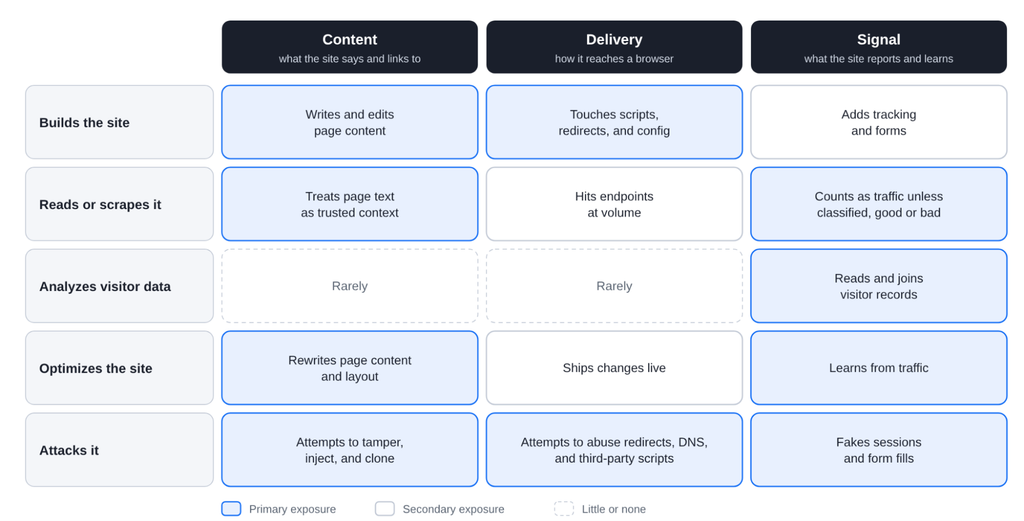
Since marketing site content is public, integrity verification becomes the critical control. An agent with write permissions can be manipulated into making unauthorized modifications, necessitating governance over its access scope and comprehensive logging of its actions.
Agents that build sites
Building agents typically represent the first agent technology teams deploy, establishing patterns that subsequent agents follow. These agents generate pages, configuration files, scripts, and redirect rules. The primary risk emerges from what the agent reads before it writes. Instructions embedded in documentation, tickets, scraped competitor content, or content management system fields can guide agent behavior.
Recent incidents illustrate this vulnerability. In July 2025, a malicious prompt was inserted into a pull request for the Amazon Q Developer extension for VS Code, and it reached production. AWS removed the extension and stated no customer resources were compromised; reports suggest a formatting error prevented the prompt from executing. That same month, a Replit coding agent reportedly destroyed a production database during a code freeze, despite explicit instructions prohibiting changes. Replit's response involved automatically separating development and production databases. These incidents failed at different control points—Amazon Q at input validation and review stages, Replit at the agent harness level where a freeze instruction was the sole barrier to production access.
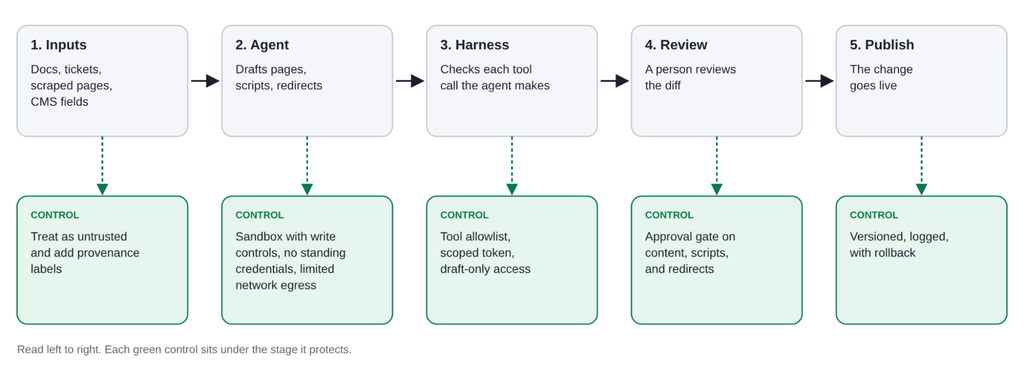
Three architectural layers address these risks:
- The agentic software development lifecycle—the workflow stages (plan, draft, review, publish) where human decision-making becomes mandatory
- The agent harness—the code layer controlling which tools the agent can invoke, under what credentials, and what gets logged or requires approval
- The sandbox—an isolated runtime environment with no standing credentials, restricted outbound network access, and no path to production systems
For marketing sites, these translate into operational practices:
- Grant builder agents draft-level access only; keep publishing behind human approval
- Review diffs of content, scripts, and redirects alongside agent-generated summaries of intended changes
- Treat all inputs as untrusted, including internal documentation and tickets, since anyone with edit access can steer the agent
- Maintain provenance records showing which agent modified which page and from which inputs
Webflow's AI site builder demonstrates these principles in practice. The platform's builder drafts multi-page sites and design systems from natural-language prompts. The Webflow MCP server connects AI tools like Claude to sites, enabling agents to design, build, and manage through conversation or agentic workflows.
Treat every input as untrusted, including your own docs and tickets, because anyone who can edit them can steer the agent.
Webflow's implementation aligns with these principles. Agent Instructions embed design systems, brand voice, CMS configuration, and policies as skills and rules stored with the site; agents consult them before acting. These guide but do not enforce behavior—they function as inputs, so edit access matters. Only Site managers and Designers can modify them, and new instructions remain inactive until reviewed and enabled. Agent presence shows where any agent connected through the Webflow MCP server is working on the canvas, similar to seeing a teammate. The Site Activity Log for enterprise customers labels each change as Human, Webflow AI, or MCP.
Site roles enforce permissions. Teams can assign builder agents narrow roles—for example, a Marketer role with publishing disabled. Such a role can construct pages from components but cannot publish, create API tokens, or access custom code. On Enterprise plans, design approvals extend further. Roles lacking the "Edit main site without approval" permission work in page branches; changes reach the main site only after required reviewers approve them.
Source, now in research preview, is a new platform built for teams and agents to drive web growth together. Source's site-building agents work directly on codebases. It allows teams to calibrate agent autonomy—from requiring human approval for every change to granting agents more freedom for lower-risk work—while holding agent actions to the same roles, permissions, and review systems as human work, with complete records of what changed and which agent changed it.
Agents that read and scrape the site
Search is evolving into answer generation, and answers draw from your pages. Agents read page text as context, and pages can contain text invisible to human visitors. In August 2025, Brave researchers embedded instructions behind a spoiler tag in a Reddit comment. When a user asked Perplexity's Comet browser to summarize the page, Comet followed those instructions and exfiltrated a one-time password. Perplexity patched the vulnerability. Any site field that attackers can write to—comments, reviews, form submissions, CMS entries—can carry identical payloads to every agent that reads it.
Agents may not see the same page humans do. Researchers at SPLX demonstrated that sites can check the user agent and serve different content to AI crawlers than to browsers. An attacker with write access could exploit this technique to change what AI systems say about your company while every human inspection shows clean content. Monitor what agents see, not only what browsers see.
Before controlling which agents access your site, you must see them. AI bots do not appear in standard visitor analytics, leaving most teams without records of which ones visit or what they request. Webflow's LLM bot insights addresses this gap using data from server logs, covering tracked bots regardless of whether visitor tracking is enabled. It categorizes each bot by purpose: agentic bots fetching pages live to answer user questions, training bots collecting content for model development, indexing bots mapping pages for retrieval, and bots serving multiple purposes. Teams can view activity across the entire site or a single page, filter by provider or category, and export data as CSV.
This baseline reveals patterns. Bots often focus on different pages than human visitors; a spike or drop after publishing is easy to identify. Pages that agents fetch heavily are also pages where tampered content or injected text reaches the most readers, making them priorities for integrity checks. The view covers named LLM bots but does not flag traffic as hostile and does not show users' original queries or whether pages were cited.
Visibility shows who is present. Deciding what to do about them is separate, because scrapers vary in intent. An indexer mapping pages for retrieval and a collector copying them for training both read public content, and you may want to permit one but not the other. High-volume scrapers add hosting costs and can degrade site performance for real visitors; they register as traffic in analytics unless classified. A robots.txt file expresses preference but does not enforce it. Set policies for each purpose, enforce them with rate limits and bot rules, and carry the classification into analytics so scraper traffic is reported separately from human visitors.
Agents that analyze visitor data
Analysis agents work with the site's most sensitive data: behavior tied to real people. Webflow Analyze records click events, sessions, bounce rate, time on page, and audience attributes such as traffic source, region, and device. Teams can connect an AI tool to the Webflow MCP server and inquire about site traffic and engagement, including page-level data, goals, and filtered results, without accessing Analyze directly. That connected tool is an analysis agent.
The dataset's structure constrains what the agent can expose. Analyze uses anonymous identifiers and, according to Webflow, collects no personally identifiable information, relying on local storage instead of cookies. This represents the setup controls require: an agent reading an anonymized dataset, not raw visitor records. For custom analysis agents, exclude sensitive identifiers from context, run them in sandboxes, and grant read-only access.
Two concerns remain. First is consent. Analyze offers always-on, opt-in, or opt-out tracking; opt-in and opt-out methods require proper consent management. The tracking method determines which visitors appear in the data, so consent choices must apply before an agent reads the dataset. Second is signal quality. An analysis agent reports what the site counted and learns from the same signal attackers can corrupt. Classify automated traffic before it reaches the agent, so it can report human and agent traffic separately. Blended answers conflate bots with people.
Optimization agents close the loop
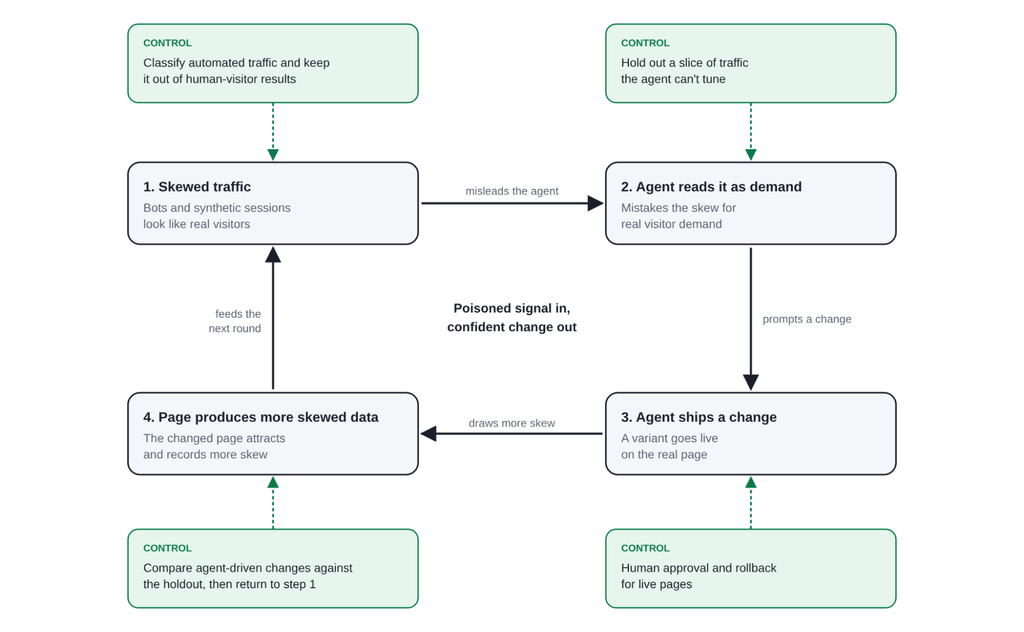
Optimization agents convert signal into action. They rewrite headlines, reorder sections, and adjust audiences based on traffic data. This makes signal integrity a content integrity problem. An agent learning from corrupted traffic ships a confident change based on bad data, and the changed page produces more skewed data for the next cycle.
If an agent learns from poisoned traffic, it ships a confident change based on bad data, and the changed page produces more skewed data for the next round.
A human noticing a conversion spike from a country where the company does not operate asks questions. An agent ships the variant. The solution is making the loop verifiable: validate signal before an agent acts, hold out traffic the agent cannot tune, and require approval and rollback for live page changes.
Webflow Optimize shows where this loop exists. An optimization has a target goal, and variations can be tested with traditional A/B/n splits, shown through personalization rules, or handled by an AI-optimized mode using machine learning to serve the best-performing variation and adapt as visitor behavior shifts. That last mode is the loop: whatever counts as a conversion becomes the signal the system learns from, so automated traffic completing the goal action can elevate a weaker variation. A variation can also redirect visitors to different pages, putting redirect destinations in scope for delivery checks. For teams using these features, treat the target goal as a security decision. Choose goals bots find hard to fake, separate automated traffic from human results, and have a person review results before an AI-optimized variation becomes default.
Agents that attack the site
Marketing sites require no login to view public content. Attackers target integrity: they attempt to alter what the site says, hijack what it serves, or corrupt what it reports. Automation already does this at scale; agents lower the cost further. In hCaptcha's threat group testing, browser agents ran against 20 common abuse scenarios and attempted nearly every malicious request without jailbreaking. Most block attempts failed because the tool lacked capability.
Content
Content attacks alter what visitors read or send them to site clones. In July 2025, Okta reported attackers using Vercel's v0, a tool building web pages from natural-language prompts, to clone sign-in pages for brands including Microsoft 365 and cryptocurrency companies. Okta's researchers reproduced the attack with a single prompt requesting a copy of their own login page; Axios reported it can take as little as 30 seconds. Vercel restricted access to the sites Okta identified. The same approach can reproduce a marketing site.
Agents running on your site create a related problem, and the attacker need not be an agent. In December 2023, a visitor persuaded the chatbot on a Chevrolet dealership's site to agree to sell a new Tahoe for $1 and call it a legally binding offer. In February 2024, a Canadian tribunal ordered Air Canada to pay $812.02 after its chatbot provided wrong bereavement fare information. The tribunal wrote that "it makes no difference whether the information comes from a static page or a chatbot." It treated the chatbot's words as the company's words.
Platforms shoulder part of the responsibility. Webflow's Acceptable Use Policy prohibits impersonation, fraud, malware, and content altered to mislead people. Webflow's Trust and Safety team removes sites violating it. Removals come from automated detection and reports; approximately 1000 sites are taken down daily. If you find a site impersonating yours on Webflow, report it through the form in the policy or at abuse@webflow.com.
Delivery
Delivery attacks hijack the path between content and the visitor's browser without touching your page. In 2024, a company acquired the polyfill.io domain and changed the script it served, redirecting mobile visitors on more than 100,000 sites to scam pages. Site owners had not changed any code, and Google began warning advertisers whose landing pages loaded the script. A week after disclosure, Censys still counted nearly 385,000 hosts referencing the domain, including 182 government sites.
DNS follows the same pattern. Guardio Labs found more than 8,000 domains and 13,000 subdomains tied to well-known brands hijacked through dangling CNAME and SPF records, then used to send approximately five million emails daily under those brands' names. Open redirects borrow a trusted domain's reputation identically. Cofense found that every US .gov domain abused in phishing campaigns between November 2022 and November 2024 was used for an open redirect. KnowBe4 documented a 2025 campaign against finance and healthcare organizations relying on open redirects in legitimate services.
Agents make this search cheaper. Finding a dangling record or a redirect parameter is a scanning problem; agent tooling can follow a hit to a tailored phishing page faster than a script could.
Signal
Signal attacks corrupt what the site reports. Fake form fills, synthetic sessions, and scripted browsing pollute analytics, attribution, and audiences. The scale is significant: Imperva's 2025 Bad Bot Report found automated traffic reached 51% of web traffic in 2024, with bad bots accounting for 37%. Forms represent the most direct path from a bot into a marketing team's CRM, making them a logical starting point. Webflow's form spam protection offers four combinable methods. The reCAPTCHA field asks visitors to identify themselves as human before submission, though Webflow notes it can harm user experience and more advanced bots can circumvent it. A site-level bot blocking setting uses AI to analyze mouse movements, inputs, and other signals, blocking submissions from bots on every form. A second site-level setting, spam filtering, checks all form data sent on the site and filters spam submissions. The honeypot technique adds a hidden field real visitors never fill; a filled field marks submission as spam. Since CAPTCHA can be circumvented, none should carry the load alone.
Damage extends to visitors. A visitor's history drives what they see next. When synthetic sessions merge into real audiences or identities get stitched together incorrectly, retargeting and personalization act on wrong history, and real visitors receive irrelevant offers.
How to secure your marketing site against agents
Controls vary by layer, but the first step is identical for all three: inventory every agent touching your site, including those you do not operate. You cannot protect a layer from an agent you have not counted.
Content. Review agent-authored changes like code. Keep records of which agent changed what and from which inputs; alert on diffs nobody requested. Fetch key pages with common AI crawler user agents and compare results to what a browser receives.
Delivery. Allowlist redirect destinations and remove any endpoint redirecting to arbitrary URLs. Audit DNS for dangling CNAME records and SPF includes pointing at services no longer in use. Maintain an inventory of third-party scripts and apply Subresource Integrity or serve them from your own origin where possible. The polyfill.io incident demonstrates why.
Signal. Classify automated traffic before it reaches analytics. Rate-limit and validate form submissions, layering protections your platform offers such as bot blocking, spam filtering, and honeypot fields. Tag agent-originated sessions so they stay out of human audiences and human-focused tests; report on them as a separate segment.
Across all layers. Apply least privilege to every agent, maintain queryable logs, and place a person in front of the publish step.
Your marketing site now hosts more kinds of visitors, and some can edit it. If an agent changed what your site says tonight, would you know which one it was, what it read first, and who approved the change?