Photonics and shared memory pools emerge as solution to AI's data bottleneck crisis
As inference workloads dominate AI infrastructure, memory constraints are forcing GPUs to sit idle. Marvell and Penguin Solutions are turning to photonic interconnects and pooled memory systems to slash the energy cost of moving data across data centers.
Data movement has become a critical constraint in artificial intelligence infrastructure, particularly as inference workloads have begun to outpace training. The problem stems from a fundamental architectural limitation: GPUs remain underutilized while waiting for data to arrive, while high-bandwidth memory, or HBM, remains locked to individual processors with no ability to share resources across systems.
Photonic interconnects represent an emerging path forward. Marvell Technology Inc. is combining optical technology with photonic memory systems to extend memory capabilities beyond individual chip boundaries. According to Preet Virk, senior vice president and general manager of the Photonic Fabric Business Unit at Marvell, this approach unlocks significant efficiency gains in data centers where enterprises have already made substantial capital investments.
In the data center today, we have a lot of room for improvement of efficiency. And when I say efficiency, I'm alluding to the wasted flops because we have GPU utilization that's very low.
Preet Virk, Marvell Technology
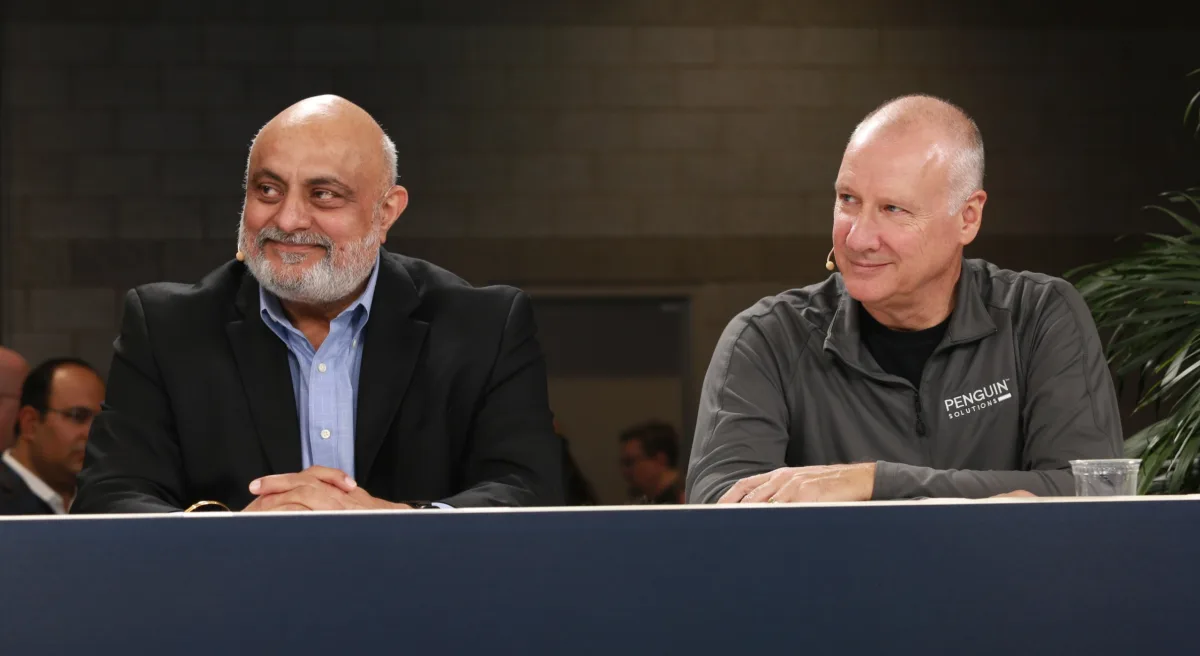
Virk and Andy Mills, vice president of advanced product development at Penguin Solutions Inc., discussed these challenges during an exclusive interview at SC26, speaking with theCUBE Research's John Furrier and Amit Eyal Govrin.
Shared pools take aim at memory bottlenecks
Penguin's MemoryAI Photonic Appliance relocates HBM into a separate enclosure positioned tens of meters away from GPU clusters, connected through Marvell's Photonic Fabric infrastructure. Each appliance provides 16 terabytes of combined HBM and DDR5 memory that multiple servers spanning different racks can access simultaneously, as Mills explained.
The challenge there is making sure your LLM doesn't forget what you started talking to it about 10 minutes ago. To do that, you need a large amount of memory, large token lengths.
Andy Mills, Penguin Solutions
The shift to optical interconnects also transforms energy consumption patterns. Copper remains viable for intra-rack connections, but traversing large pods containing thousands of GPUs demands optical solutions, Virk noted. He highlighted a striking statistic: more than 80 percent of traffic in scaled-up networks consists of memory transactions. Implementing shared memory pools means much of this data transfer becomes unnecessary.
Within data movement, the memory transactions are a place to focus on. So with this solution versus a copper-based data movement, we could immediately get to a quarter of the energy, picojoules per bit, of data movement.
Preet Virk, Marvell Technology
Emerging AI agents are intensifying memory demands by generating substantially higher volumes of token requests compared to traditional human user interactions. As inference operations expand across additional racks and geographic sites, Mills views shared memory pools as the essential solution for addressing memory constraints at scale.
https://www.youtube.com/embed/g0TFbXUCiBY?start=1&feature=oembed
If anything, distributed encourages shared because you don't want to recompute. The whole thing about KV cache was a huge success because it stops recomputation of the same data. And when you can share that data on a broader base and wider across more racks, your efficiencies go up as well.
Andy Mills, Penguin Solutions