Vast Data argues fragmented AI pipelines create data sovereignty risks
As enterprises move AI inference closer to sensitive information, modular infrastructure struggles to maintain alignment between embeddings, permissions and source data, according to the company's systems engineering leadership.
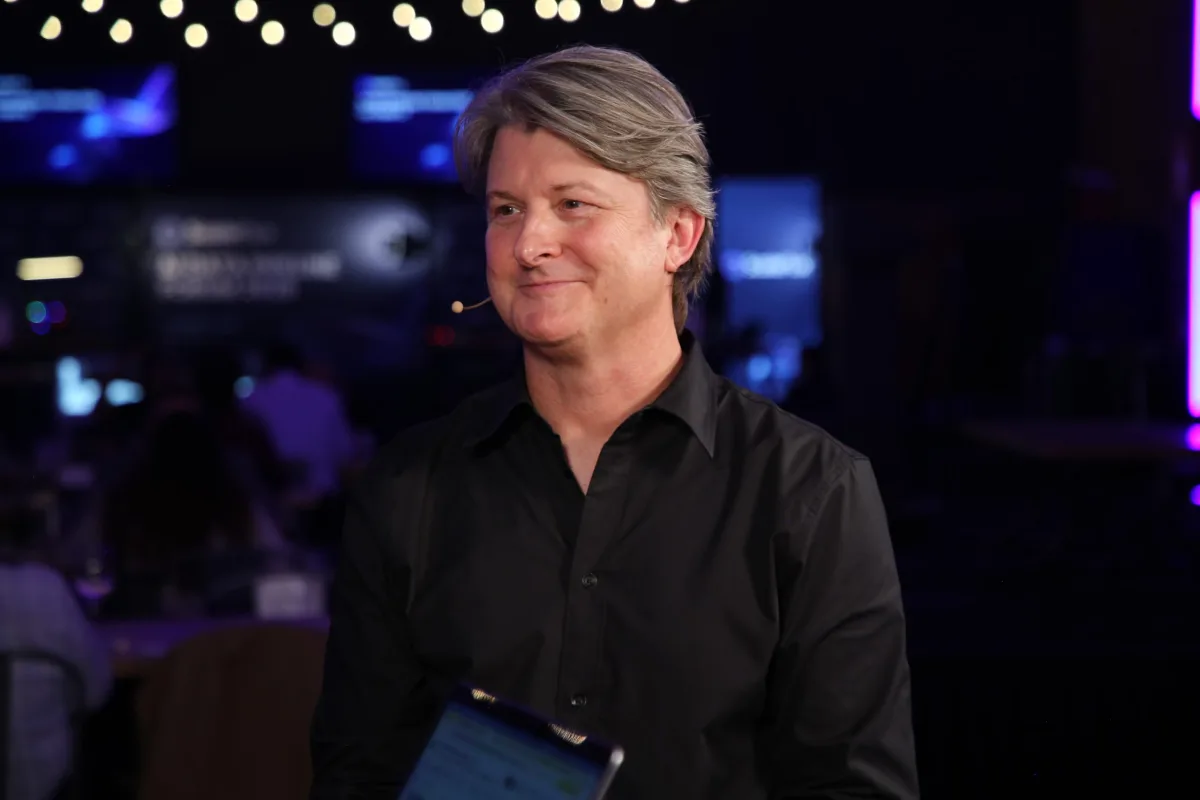
Data sovereignty has emerged as an architectural challenge for enterprises deploying artificial intelligence inference on their most sensitive information. When organizations assemble AI pipelines from disparate tools, they face difficulties maintaining consistency across embeddings, access permissions and underlying data sources, which keeps many valuable datasets outside the reach of AI systems.
The industry's transition from model training to inference deployment has reshaped infrastructure requirements, driving growth for Vast Data Inc. The company closed a funding round in April 2026 that valued it at $30 billion and raised approximately $1 billion. Managing user identification, access controls and regulated data now ranks among the core demands on AI infrastructure, according to Vaughn Stewart, vice president of systems engineering at Vast.
There's kind of different philosophical concepts in the market, right? One is the bespoke model … a best-in-breed of every piece in an agentic pipeline. And what we see there is just too much exposure to having data that's maybe not in sync between being updated versus the vector embeddings, or maybe not in sync between the user access controls on the source data versus what's provided through an inference query.
Vaughn Stewart, Vast Data
Stewart made these remarks during an appearance at the AI Data Pipeline Forum, where he spoke with John Furrier of theCUBE Research in an exclusive broadcast on theCUBE, the livestreaming studio operated by SiliconANGLE Media.
Data sovereignty strains modular pipeline architectures
Infrastructure providers operating in the neocloud space face little tolerance for underperformance. Organizations readily abandon and replace software that fails to meet their needs, marking a departure from the storage industry's traditional vendor lock-in dynamics, Stewart observed. Vast's approach employs a disaggregated, shared-everything architecture that merges the functions of storage systems and data-processing platforms into a single integrated offering.
No one ever referred to a Hadoop data lake, or a Kafka event bus as a storage platform, but it stored petabytes or tens of petabytes of data. So, we're able to conflate the functions of these two systems in a tightly integrated way that delivers performance.
Vaughn Stewart, Vast Data
When asked about competitive threats, Stewart identified not a specific rival but rather "a legacy mindset" centered on assembling agentic pipelines from interchangeable best-of-breed components. This modular approach carries a significant drawback: data must traverse multiple systems during processing, and access controls frequently become disconnected in the process.
I think this construct of, 'I can build and move this massive volume of data and all these connections through a pipeline and have it be near-real-time,' I think, is a fallacy when we start to talk about the needs for serving parallel requests, parallel functions at mass scale.
Vaughn Stewart, Vast Data
Approximately half of the world's data remains housed in corporate data centers or colocation environments due to sensitivity and regulatory requirements, according to Stewart. Legal constraints frequently prevent this data from reaching public cloud frontier models, making data sovereignty a non-negotiable requirement. Vast introduced DataEnclave in September 2026 as its response to this challenge—a confidential AI runtime developed in partnership with Nvidia Corp. and Cohere Inc. The system executes models within secured virtual machines, mandates remote cryptographic attestation before releasing keys and maintains all access records in a tamper-resistant database.
https://www.youtube.com/embed/-pK2jtQ26KE?feature=oembed
If there's no attestation, there's no access to the keys for the model and/or the data. This is what we believe is going to allow us to bring frontier models to these highly secure datasets today and kind of bridge that last mile of opening up AI tools, technologies and capabilities.
Vaughn Stewart, Vast Data